Why Your AI Needs a Standard "Plug"
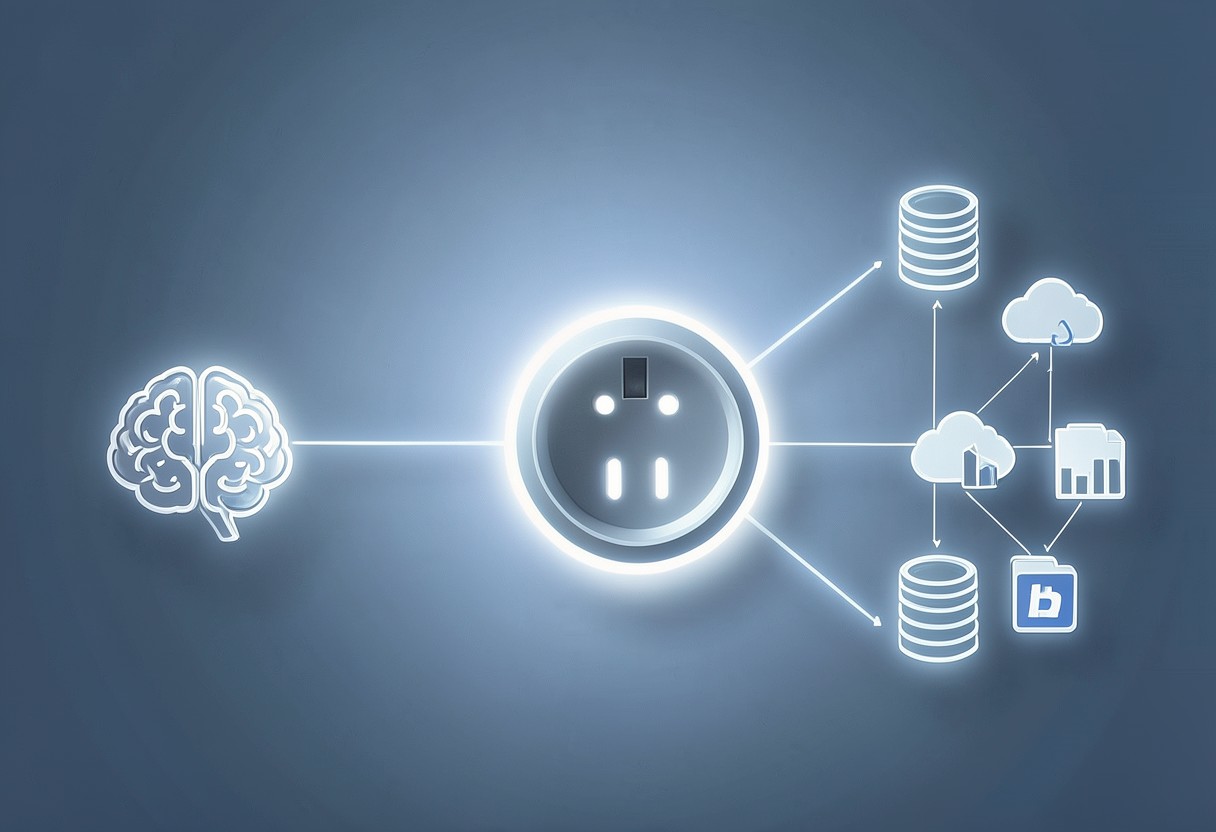
Imagine you want your company's AI assistant to answer questions like "what are our total orders this month?", summarize a proposal stored in Google Drive, or check the latest pull requests on GitHub. Until recently, each of those needs meant a separate custom integration: one connector for the database, another for file storage, another for the team chat app. If you use several AI applications, that work has to be repeated for every single one. The result is the classic M×N problem: M AI applications times N data systems equals a pile of integration code that is expensive to maintain.
Model Context Protocol (MCP) exists to cut through this problem. According to its official specification, MCP is an open protocol that enables seamless integration between LLM applications and external data sources and tools. The idea is simple: build one MCP server for a system, and every AI application that supports MCP can use it right away. The M×N problem becomes M+N.
The specification also notes that MCP draws inspiration from the Language Server Protocol (LSP), the standard that lets programming language support work across many code editors. MCP does the same for the AI application ecosystem: it standardizes how additional context and tools are plugged in.
Architecture: Hosts, Clients, and Servers
MCP uses JSON-RPC 2.0 messages to communicate between three core roles:
| Role | Definition in the Specification | Real-World Example |
|---|---|---|
| Host | The LLM application that initiates connections | An AI chat app or an AI-powered IDE |
| Client | A connector inside the host application | The connection module a host creates for each server |
| Server | A service that provides context and capabilities | An MCP server for PostgreSQL, GitHub, or the file system |
A single host can run multiple clients at once, and each client maintains a dedicated session with one server. The base protocol has three defining traits: the JSON-RPC message format, stateful connections, and capability negotiation between server and client when a connection opens. In other words, at the start of every session both sides declare which features they support.
Here is a simple JSON-RPC request from a client calling a tool named query:
{
  "jsonrpc": "2.0",
  "id": 1,
  "method": "tools/call",
  "params": {
    "name": "query",
    "arguments": { "sql": "SELECT COUNT(*) FROM orders WHERE created_at >= '2026-09-01'" }
  }
}
Because the format is standardized, developers don't need to learn a different API for each AI application. Follow the protocol schema, and your server works with any host that supports MCP.
The Three Server Primitives: Tools, Resources, and Prompts
The MCP specification defines three core features a server can offer to clients:
| Primitive | Purpose | Business Example |
|---|---|---|
| Tools | Functions the AI model can execute | Running a database query, creating an issue, sending a message |
| Resources | Context and data for the user or the AI model to use | SOP documents, table schemas, configuration files |
| Prompts | Templated messages and workflows for users | A "generate weekly sales report" template |
The key difference is who is in control. Tools are invoked by the model when needed, resources are data surfaced as context, and prompts are usually picked directly by the user as ready-made templates.
Clients can also offer features back to servers: Sampling (the server asks the host to run an LLM interaction), Roots (the server asks which URI or filesystem boundaries it may operate in), and Elicitation (the server requests additional information from the user). The specification further provides supporting utilities such as progress tracking, cancellation, error reporting, and logging.
Ready-Made MCP Servers: PostgreSQL, Google Drive, GitHub, Slack, and More
The official modelcontextprotocol/servers repository hosts reference implementations you can try immediately. Pay attention to their status, though, because several popular servers have since been archived:
| Server | Capability | Status in the Official Repository |
|---|---|---|
| PostgreSQL | Read-only database access with schema inspection | Archived (servers-archived) |
| Google Drive | File access and search for Google Drive | Archived (servers-archived) |
| GitHub | Repository management, file operations, GitHub API integration | Archived |
| Slack | Channel management and messaging | Archived, now maintained by Zencoder |
| Filesystem | File operations with configurable access controls | Active (reference) |
| Git | Reading, searching, and manipulating Git repositories | Active (reference) |
| Fetch | Fetching and converting web content for LLMs | Active (reference) |
| Memory | Knowledge graph-based persistent memory | Active (reference) |
To discover more servers, the repository points to the MCP Registry at registry.modelcontextprotocol.io. TypeScript-based servers can be launched with npx, while Python servers run via uvx or pip. Here is an example configuration for a host such as Claude Desktop:
{
  "mcpServers": {
    "postgres": {
      "command": "npx",
      "args": ["-y", "@modelcontextprotocol/server-postgres", "postgresql://localhost/mydb"]
    }
  }
}
One important caveat: the official repository states clearly that its servers are reference implementations meant for education, not production-ready solutions. Developers are expected to evaluate their own security requirements based on their specific threat model.
Security Warnings from the Official Specification
MCP's power comes from enabling arbitrary data access and code execution paths. The official specification stresses that this power brings security and trust considerations every implementor must address. Its four key principles are:
- User consent and control: users must explicitly consent to and understand all data access and operations, and must stay in control of what is shared.
- Data privacy: hosts must obtain explicit consent before exposing user data to servers, and must not transmit resource data elsewhere without permission.
- Tool safety: tools represent arbitrary code execution and must be treated with appropriate caution. Descriptions of tool behavior, including annotations, should be considered untrusted unless they come from a trusted server. Hosts must obtain explicit user consent before invoking any tool.
- LLM sampling controls: users must approve every sampling request, including the prompt sent and the results the server can see.
The specification also acknowledges that MCP cannot enforce these principles at the protocol level. The responsibility lies with you as the implementor. In practice, we recommend:
- Using a dedicated read-only database user for servers like PostgreSQL.
- Applying least privilege to API tokens (for example, a GitHub personal access token with minimal scopes).
- Storing credentials in environment variables, never in code.
- Requiring human-in-the-loop confirmation for tools that modify data.
- Auditing third-party servers before installing them, just as you would any other dependency.
Getting Started in Your Business
Start with a small, low-risk use case, such as an AI that only reads internal documentation or sales reports. Once your consent flow and logging are proven, expand to tools that can write data. Keep in mind that the MCP specification keeps evolving: the official repository already contains a schema version newer than 2025-06-18, so always check the latest revision before building a production server.
Conclusion
MCP changes how AI connects to business systems: from a stack of custom connectors to a single open standard built on JSON-RPC, with a clear host, client, and server architecture. With three primitives (tools, resources, prompts) and a growing ecosystem of servers, development teams can move much faster. The golden rule stays the same, though: treat every tool as code execution, require explicit consent, and keep access as narrow as possible. If you need help setting up secure hosting infrastructure for your internal MCP servers, the katili.dev team is ready to help.