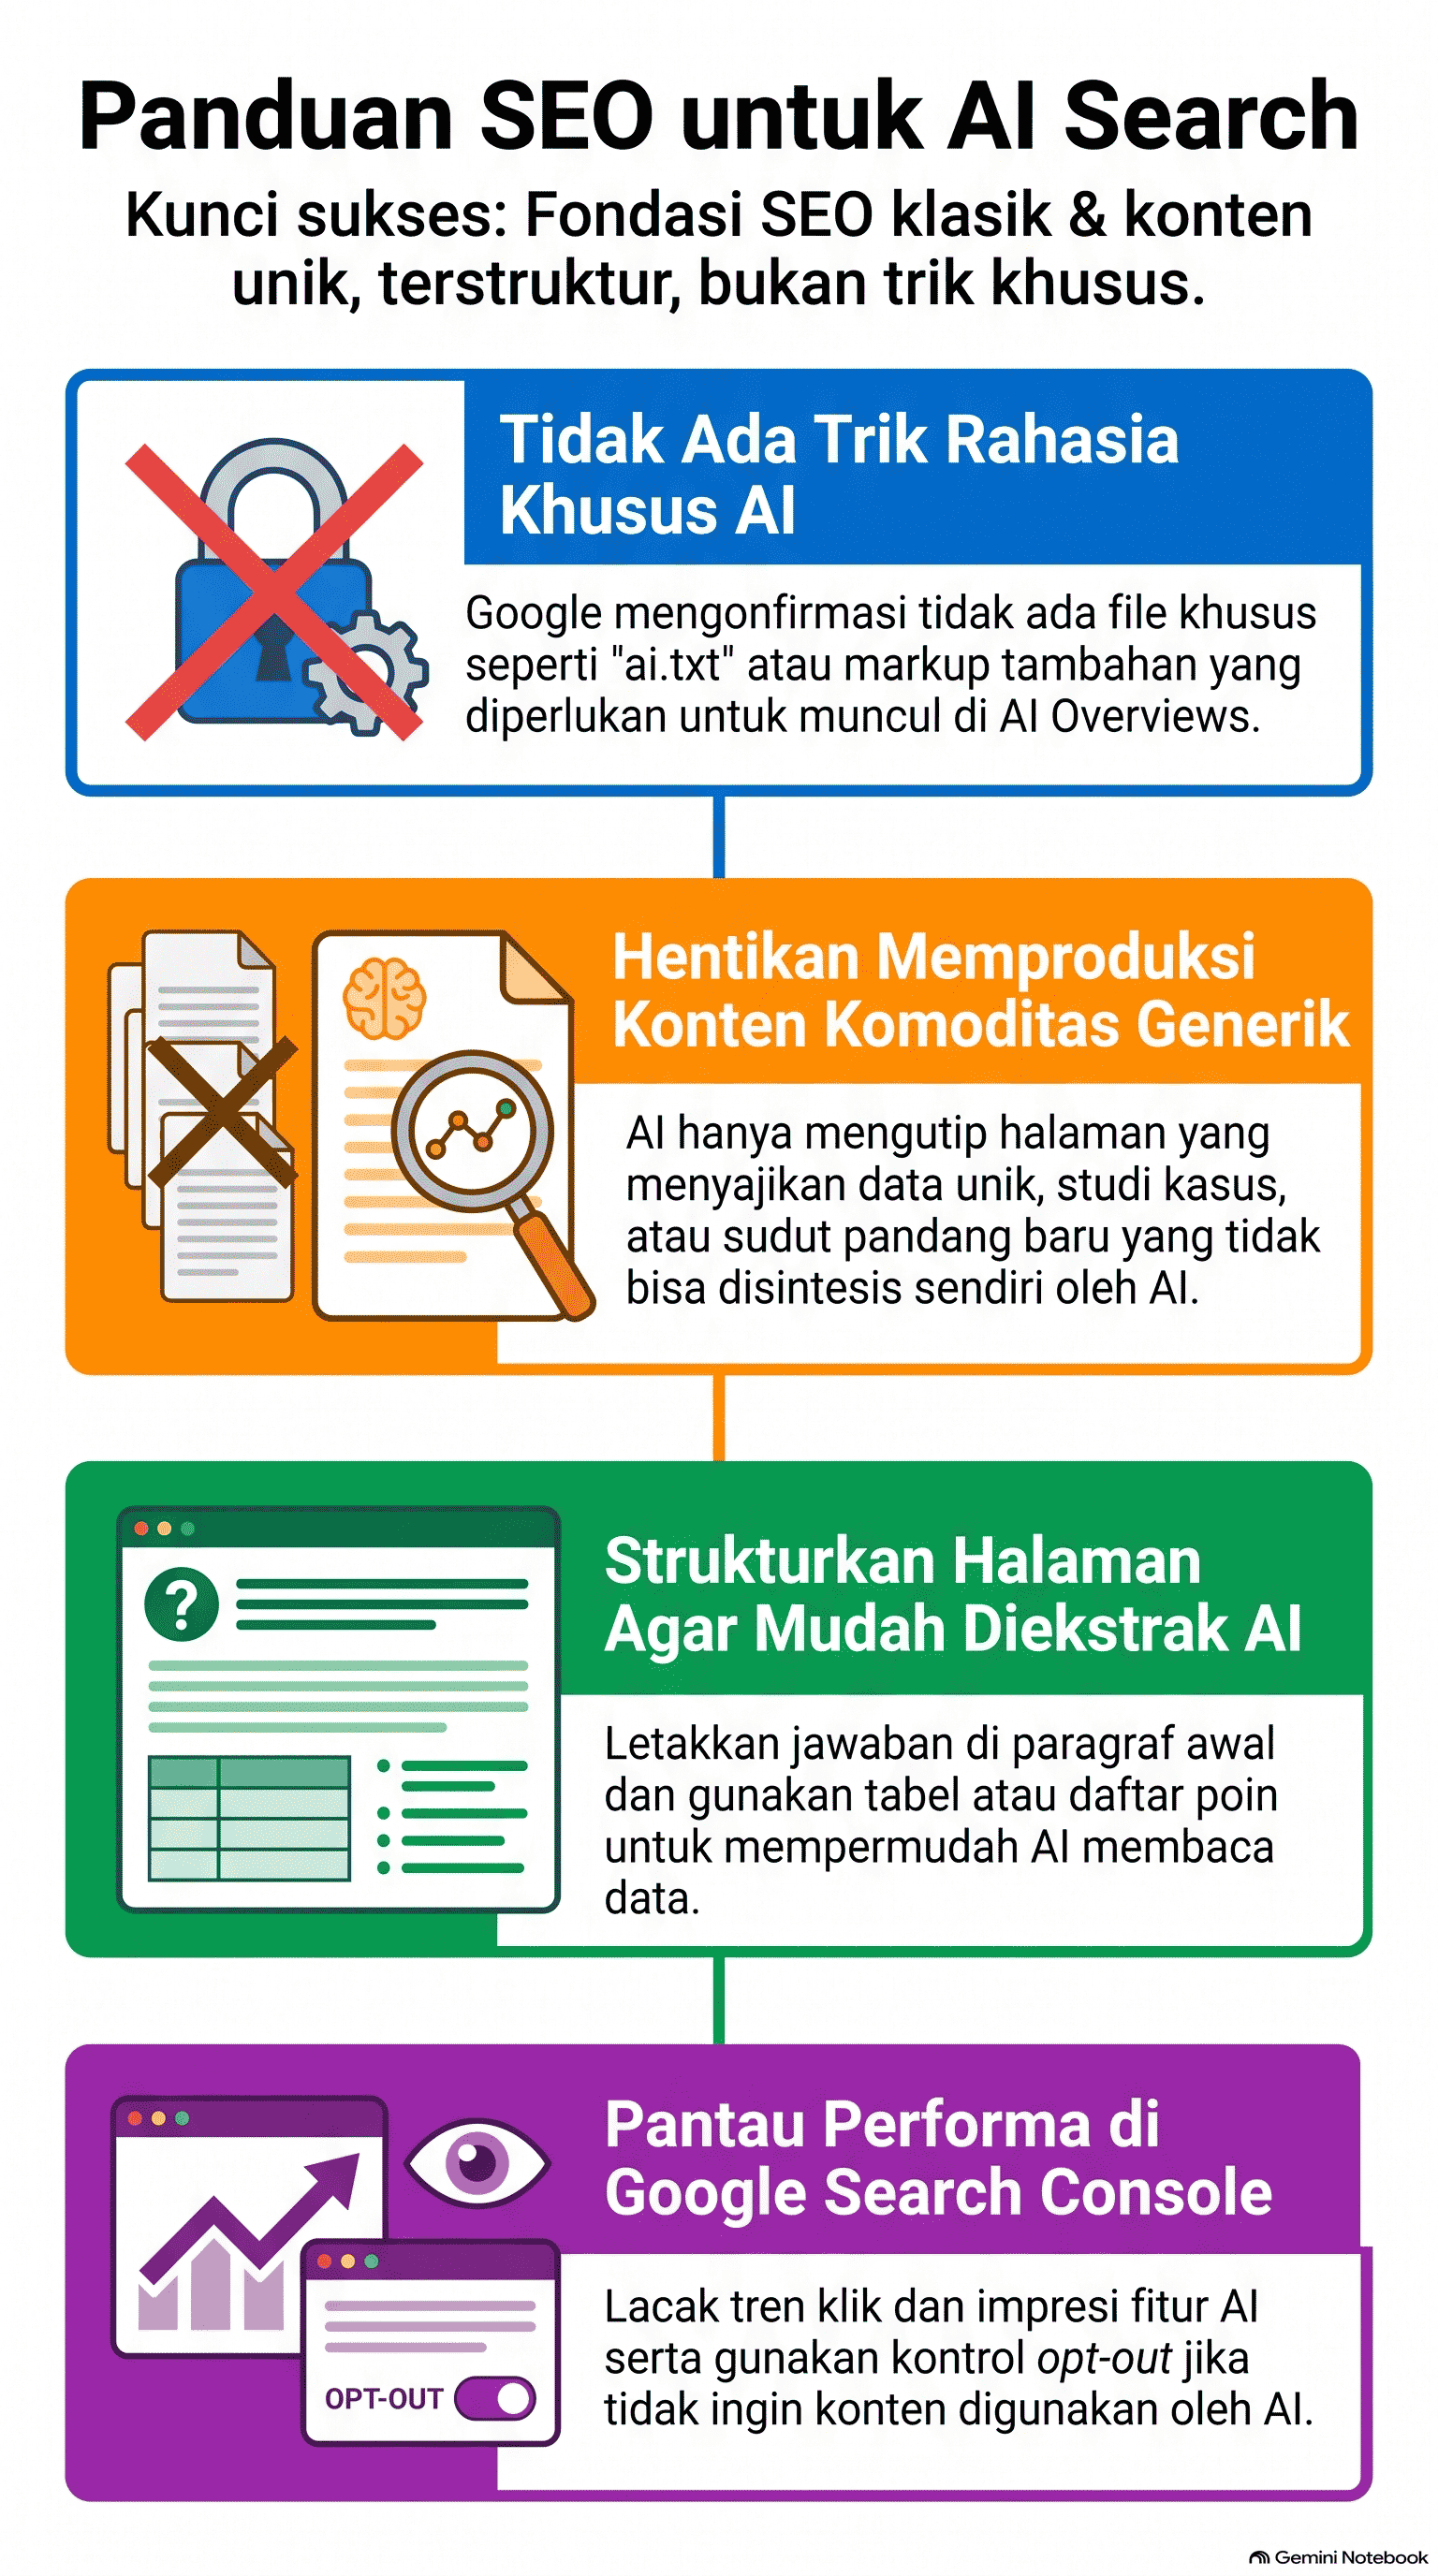
Plenty of businesses want to publish content consistently, yet stall by week three. Not because they run out of ideas, but because every article feels like starting from scratch: research keywords again, settle on a tone again, check formatting again. At katili.dev we use AI agents to cut that repetitive work while keeping the decisions that matter in human hands.
This article opens up that workflow: from keyword research, to how we package editorial standards as a skill, to the checkpoints where a human must step in.
Why a Workflow, Not Just a Prompt
We have written before that AI is fundamentally a pattern machine: it learns statistical patterns from data and is very good at predicting the most likely continuation, but it does not truly understand what it writes. The practical consequence is that AI can produce text that sounds convincing while the data is wrong or the perspective is flat.
So we do not rely on one long prompt retyped every time. We built a clear flow: which stages the agent handles, which stages humans handle, and which rules always apply.
Stage 1: Keyword Collection, SERP Analysis, and Intent Mapping
Research starts from real questions our clients' customers ask, not from a list of high-volume keywords. The steps:
- Keyword collection. We gather topics from customer questions, the client's services, and the phrasing people actually use when searching. The AI agent helps expand this list into clusters of related topics.
- SERP analysis. For every core topic we look at the first page of results: what type of content shows up (tutorials, lists, comparisons), how deep it goes, and what is left unanswered. Backlinko notes that first-page Google results average around 1,400 words, and that comprehensive topic coverage correlates with rankings. We treat that number as a picture of depth, not a word count to chase.
- Intent mapping. Each keyword gets a search intent label: informational, commercial, or transactional. Intent dictates format. Someone searching "how to choose hosting" needs a guide, not a pricing page.
The research is summarised in a spreadsheet content plan: one row per article with title, description, category, language, references, and prompt. The spreadsheet is imported into the admin panel so each article's status can be tracked on a calendar.
| Research stage | Done by the agent | Decided by a human |
|---|---|---|
| Keyword collection | Expanding and clustering topics | Picking topics relevant to the client's business |
| SERP analysis | Summarising patterns in existing content | Identifying gaps and added value |
| Intent mapping | Proposing intent labels | Making sure the format fits the reader |
Stage 2: Packaging Editorial Standards as a Skill
This is the part that changed output consistency the most. Instead of pasting style rules into every conversation, we write them once as an Agent Skill.
According to Anthropic's documentation, a Skill is a filesystem-based resource containing instructions, metadata, and optional resources (scripts, templates) that loads on demand. Every Skill has a SKILL.md file with YAML frontmatter holding a name and a description. Loading happens in stages (progressive disclosure):
- Level 1 – Metadata: just the name and description, about 100 tokens per Skill, always loaded.
- Level 2 – Instructions: the
SKILL.mdbody (under 5k tokens), read only when the Skill is triggered. - Level 3 – Resources: reference files and scripts accessed only when needed; for scripts, only their output enters the context.
In Claude Code, custom Skills simply live in .claude/skills/ (per project) or ~/.claude/skills/ (personal). Our editorial Skill covers article structure, minimum length, heading rules, tone, table formatting, thumbnail prompt rules, and the requirement to list references. Because these rules live in one place, revising a standard happens once and applies to the very next article.
One security note from the same documentation: only use Skills from trusted sources, since a Skill can direct the agent to run tools or code. Skills that fetch data from external URLs also deserve an audit, because fetched content may contain malicious instructions.
Stage 3: From Brief to a Bilingual, Import-Ready Draft
Once the plan and the Skill are in place, the flow looks roughly like this:
- The agent reads one content plan item: title, description, required points, and reference URLs.
- The agent opens every reference URL and uses it as the factual basis. Sources that fail to load are skipped, never invented.
- The agent writes two versions, Indonesian and English, as a single JSON file containing title, category, tags, excerpt, SEO meta, source URLs, a thumbnail prompt, and Markdown content.
- The file is validated automatically: structure, length, headings, and required fields.
- The file is imported as a draft, not published, and the plan item is marked done.
A fixed file format turns importing into deterministic machine work, so human energy goes into the substance.
Stage 4: Human Checkpoints
A draft from the agent is not a finished product. There are three things we always check ourselves:
- Data verification. Every number, feature name, and technical claim is matched against its original source. A pattern machine can be wrong with complete confidence.
- Point of view. Does the article take a clear position and make recommendations, or does it merely summarise what already exists? Perspective is what separates a client's content from thousands of similar articles.
- Real-world examples. First-hand experience, figures from our own projects, or obstacles we actually hit can only be added by the people who lived them.
This lines up with the quality signals Backlinko summarises: high-quality content, expertise, authoritativeness and trustworthiness (E-A-T), and user behaviour such as dwell time and pogosticking, where visitors bounce straight back to the results because they did not find an answer.
Stage 5: Mistakes We Avoid
Publishing without checking sources. An article quoting a wrong figure damages trust faster than an article that never ships. That is why every agent output lands as a draft and must pass review.
Content with no added value. Backlinko stresses that syndicated, scraped, or duplicate content tends to rank poorly, and that valueless auto-generated content can be penalised. An article that merely rearranges Google's first page gives readers, and search engines, no reason to choose it.
Chasing word counts. Length is a side effect of covering a topic thoroughly, not a goal. Nine hundred words that answer the question beat two thousand that go in circles.
Closing
AI agents make routine content production realistic: faster research, a more consistent voice, and files that are always ready to import. But an article's value still comes from people: verified data, a clear point of view, and real experience. A good workflow is not about handing everything to a machine; it is about putting machines and humans on the work each does best.
If you want to build a similar content pipeline for your business, the katili.dev team is happy to help design it.