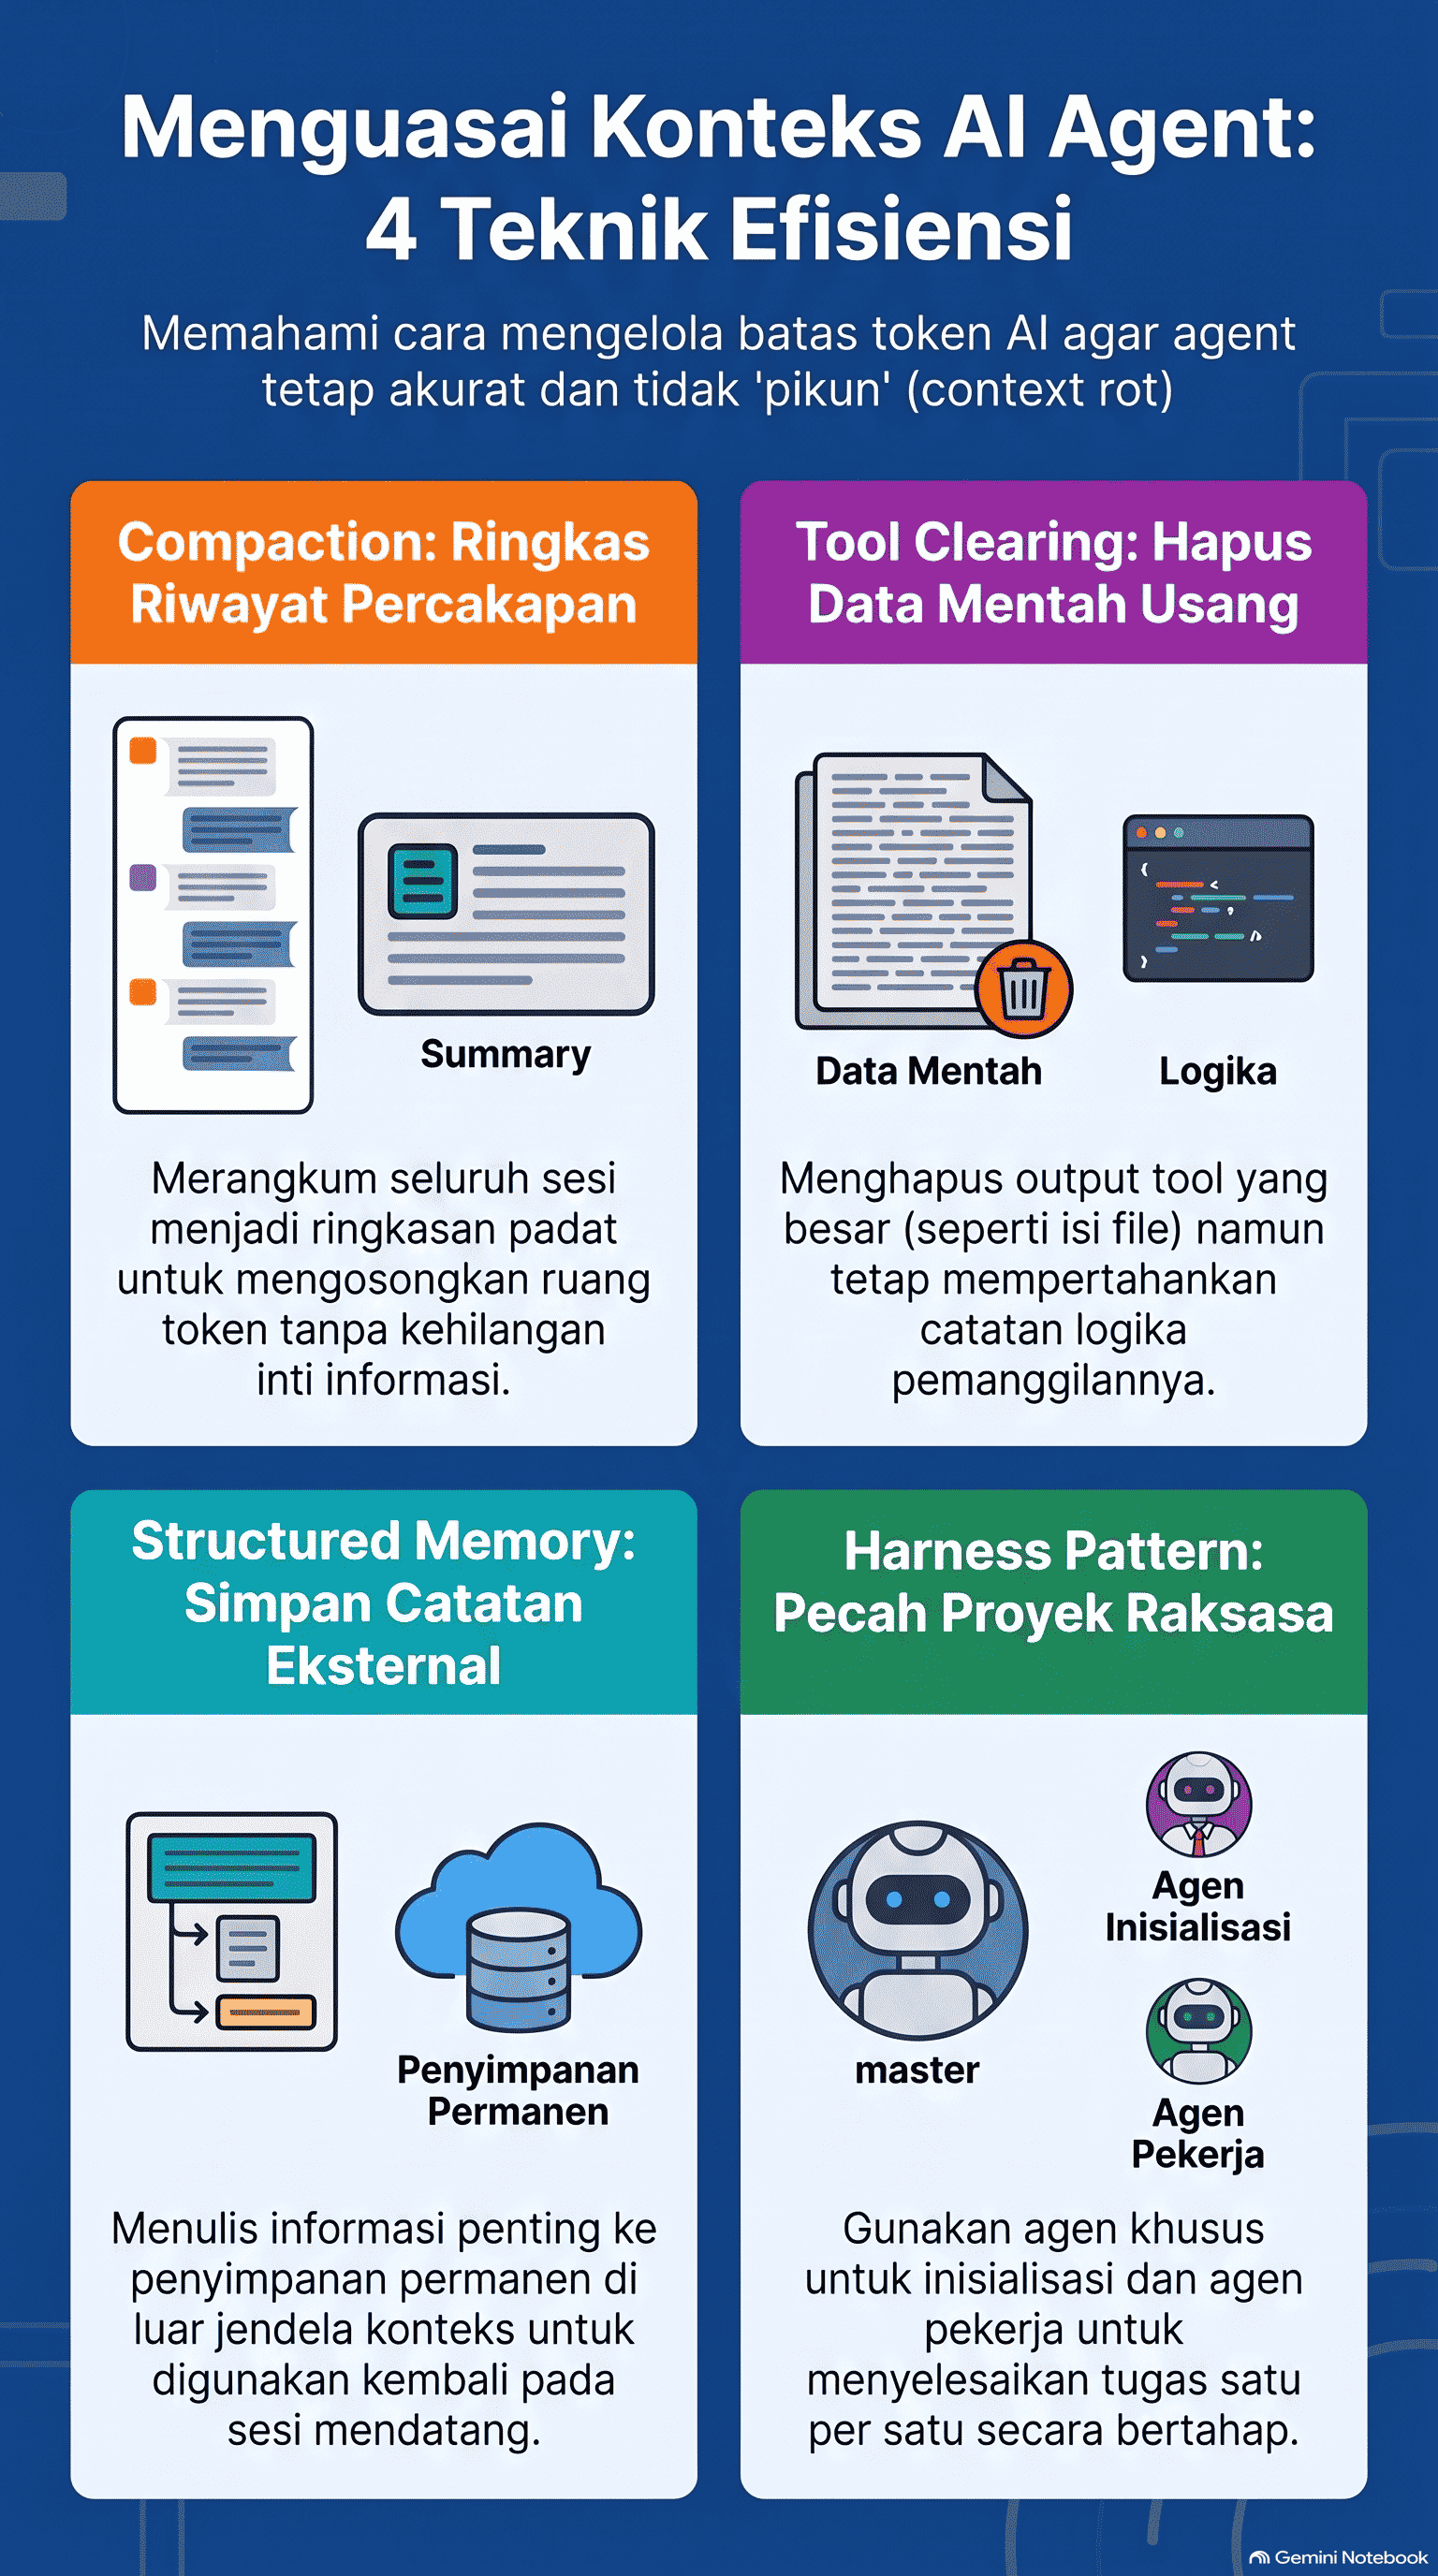
Why Build Your Own MCP Server?
Sooner or later, every team that experiments with AI agents hits the same wall: the model is smart, but it knows nothing about your customers, your invoices, or your service status. The Model Context Protocol (MCP) is the open standard for closing that gap. The specification describes it as a protocol that connects LLM applications to external data sources and tools, using JSON-RPC 2.0 messages between three roles: hosts (the LLM application), clients (connectors inside the host), and servers (the services that provide context and capabilities). A server can offer three kinds of features: resources, prompts, and tools.
Before you start, it helps to look at the official modelcontextprotocol/servers repository. It contains reference servers such as Filesystem, Git, Fetch, and Memory, but it states plainly that they are educational examples demonstrating SDK usage, not production-ready solutions. You are expected to evaluate your own threat model. That is exactly what this guide is about: building a small, deliberate server over real business data. Our running example is a hosting company's billing database.
1. Choose What to Expose: Read-Only First, Writes Much Later
The most common mistake is starting with a generic tool like run_sql or call_api. It feels flexible, but it hands the model the entire surface of your system and makes it impossible to reason about what an agent can actually do.
Instead, start from the questions people already ask your team every week, and expose one narrow tool per question. Tools in MCP are model-controlled: the model discovers and invokes them on its own based on the conversation. The spec says there SHOULD always be a human in the loop who can deny invocations, but your server cannot verify that every client actually does this. So design as if the agent will call anything you expose.
| Phase | What to expose | Billing example |
|---|---|---|
| 1 | Narrow read-only lookups | get_invoice, search_invoices, get_service_status |
| 2 | Read-only aggregates | summarize_overdue_by_month |
| 3 | Reversible, low-impact writes | add_internal_note |
| 4 | Consequential writes (only after audit data) | issue_refund, suspend_service |
Notice that the archived PostgreSQL reference server was also scoped to read-only database access with schema inspection. Read-only is the sane default. Move to the next phase only after your audit logs show how agents actually use the tools you already have.
2. Project Setup with the Official SDK
Official MCP SDKs exist for TypeScript, Python, Go, Java, Kotlin, C#, PHP, Ruby, Rust, and Swift. The examples below use the TypeScript SDK with Zod for schemas:
mkdir billing-mcp && cd billing-mcp
npm init -y
npm install @modelcontextprotocol/sdk zod
npm install -D typescript @types/node
The minimum server skeleton is small. It creates a server, registers tools, and connects a transport. For a local, single-user server, stdio is the simplest transport:
// src/index.ts
import { McpServer } from "@modelcontextprotocol/sdk/server/mcp.js";
import { StdioServerTransport } from "@modelcontextprotocol/sdk/server/stdio.js";
import { z } from "zod";

const server = new McpServer({
  name: "billing-mcp",
  version: "0.1.0",
});

// tools are registered here (see next section)

async function main() {
  const transport = new StdioServerTransport();
  await server.connect(transport);
  console.error("billing-mcp running on stdio"); // stderr, never stdout
}

main().catch((err) => {
  console.error(err);
  process.exit(1);
});
One detail catches almost everyone: with the stdio transport, stdout is the protocol channel. Any stray console.log corrupts the JSON-RPC stream, so send logs to stderr. To try the server, compile it and register it in a client. The servers repository shows the Claude Desktop configuration format:
{
  "mcpServers": {
    "billing": {
      "command": "node",
      "args": ["/path/to/billing-mcp/build/index.js"],
      "env": { "BILLING_DB_URL": "postgres://mcp_readonly@localhost/billing" }
    }
  }
}
A practical note: the specification keeps evolving. This article follows the 2025-06-18 revision, while the specification repository already publishes newer schema revisions. Pin your SDK version and check which protocol version it negotiates before you upgrade.
3. Defining a Tool: Schema, Description, and Why the Description Is the Interface
Per the specification, a tool definition consists of a name, an optional title, a description, an inputSchema (JSON Schema for parameters), an optional outputSchema, and optional annotations. Here is a real tool:
server.registerTool(
  "search_invoices",
  {
    title: "Search invoices",
    description:
      "Search one customer's invoices in the billing system. Use this when the user asks about " +
      "unpaid bills, payment history, or whether a specific invoice was paid. Returns at most " +
      "`limit` invoices, newest first, amounts in IDR. Does NOT return line items; call " +
      "get_invoice with an invoice id for those.",
    inputSchema: {
      customerId: z.string().describe("Internal customer ID, e.g. CUST-1042"),
      status: z.enum(["unpaid", "paid", "overdue"]).optional()
        .describe("Filter by payment status. Omit to include all statuses."),
      limit: z.number().int().min(1).max(25).default(10)
        .describe("Maximum number of invoices to return (1-25)."),
    },
    outputSchema: {
      invoices: z.array(z.object({
        id: z.string(),
        issuedAt: z.string(),
        dueAt: z.string(),
        amountIdr: z.number(),
        status: z.string(),
      })),
      totalMatching: z.number(),
      truncated: z.boolean(),
    },
    annotations: { readOnlyHint: true, openWorldHint: false },
  },
  handleSearchInvoices,
);
For a human developer, the description is documentation. For an agent, the description is the interface. The model decides whether to call your tool, and with what arguments, almost entirely from the name, description, and parameter descriptions. A good description answers four questions:
- When should this tool be used (and when should another tool be used instead)?
- What does it return, including units, ordering, and limits?
- What does it not do, so the agent does not expect line items it will never get?
- What format do the arguments take, with a concrete example ID?
Constrain inputs in the schema rather than in prose. An enum for status and a max(25) on limit prevent entire classes of bad calls. Treat changes to descriptions like API changes: review them, version them, and test them with a real agent.
4. Returning Results an Agent Can Actually Use
An agent pays for every token you return, and a flood of raw rows makes it worse at the task, not better. Return only the fields the question needs, cap the size, and tell the agent when data was cut off.
The 2025-06-18 spec added structured tool output. A result can carry structuredContent, a JSON object, and if you declare an outputSchema, the server MUST return structured results that conform to it. For backward compatibility, a tool that returns structured content SHOULD also include the serialized JSON in a text block:
async function handleSearchInvoices({ customerId, status, limit }) {
  const customer = await db.findCustomer(customerId);
  if (!customer) {
    return {
      isError: true,
      content: [{
        type: "text",
        text: `No customer with ID ${customerId}. IDs look like CUST-1042; ` +
              `use find_customer to look one up by email first.`,
      }],
    };
  }

  const { rows, total } = await db.searchInvoices({ customerId, status, limit });
  const result = {
    invoices: rows.map((r) => ({
      id: r.id,
      issuedAt: r.issued_at,
      dueAt: r.due_at,
      amountIdr: r.amount,
      status: r.status,
    })),
    totalMatching: total,
    truncated: total > rows.length,
  };

  return {
    content: [{ type: "text", text: JSON.stringify(result) }],
    structuredContent: result,
  };
}
The spec distinguishes two kinds of errors. Protocol errors are standard JSON-RPC errors for unknown tools, invalid arguments, or server failures. Tool execution errors are returned inside the result with isError: true, for API failures, invalid input data, or business-logic problems. The second kind is visible to the model, so write it for the model: say what went wrong and what to try next. "No customer with ID X; use find_customer first" lets the agent recover. "Error 500" does not.
One practical nuance: when a tool declares an outputSchema, return error results as plain text content without structuredContent. SDK issue trackers show that some client versions validate structuredContent against the output schema even on error results, which can turn your helpful message into a validation failure.
5. Security Checklist
The specification is explicit that MCP opens powerful data-access and code-execution paths, and that tools represent arbitrary code execution to be treated with caution. At the server level, it says servers MUST validate all tool inputs, implement proper access controls, rate limit tool invocations, and sanitize tool outputs. Translate that into a concrete checklist:
| Area | What to do |
|---|---|
| Authorization | For remote (HTTP) servers, use the spec's OAuth-based authorization; accept only tokens issued for your server and never forward the client's token to downstream APIs. For local stdio servers, load credentials from the environment. |
| Scoping | Connect with a dedicated database user that can only SELECT from specific views. Enforce tenant or customer scoping in the query, not in the prompt. Apply hard row limits and timeouts. |
| Untrusted annotations | Annotations like readOnlyHint are hints. Clients MUST treat them as untrusted unless the server is trusted, so never rely on them as a safeguard. Enforce read-only at the database permission level. |
| Untrusted data | Free-text fields such as customer notes can contain prompt-injection text. Sanitize or clearly delimit them before returning. |
| Audit logging | Log every call: caller identity, tool name, redacted arguments, result size, duration, and error status. Clients SHOULD log tool usage too, but keep your own trail. |
Closing
Your first MCP server does not need to be clever. It needs to be narrow, read-only, well described, economical with tokens, and locked down at the database layer. Start with two or three lookups your team answers manually every day, watch the audit log for a few weeks, and only then consider the first write operation. If you need help hosting or building these internal integrations, that is exactly the kind of work we do at katili.dev.